Multimodal content understanding: the whole artefact, not one frame of it
Content understanding services take a document, image, audio file or video and return structured output for the whole thing, such as the scenes of a video with a summary for each.


What is multimodal content understanding?
Labelling a picture and understanding a scene are different jobs. Content understanding services combine several models behind one call: they read the text, listen to the audio, look at the frames, and return one structured result in a format you define.
The convenience has a price: the provider decides which models work inside. Check that before you depend on it, especially if you need to know which model answered and keep that answer stable next quarter.
Four ways to run it
Each of the big clouds offers it as a managed service, and you can also run it yourself. Same task, a different bill and a different console.
Amazon Bedrock Data Automation[1]
The managed service on AWS that extracts structured output from documents, images, audio and video in one call.
Official documentation →Azure Content Understanding[2]
The service in Microsoft Foundry with analyzers for documents, images, audio and video, generally available since November 2025.
Official documentation →Document AI (closest for documents)[3]
The closest managed match on Google Cloud for documents; for media you combine it with other Google APIs.
Official documentation →Your own pipeline[4]
Split with FFmpeg, transcribe with Whisper, caption frames with an open vision model, summarise with an open LLM, and parse documents with Docling (MIT). More work, and every model choice is yours.
Project page →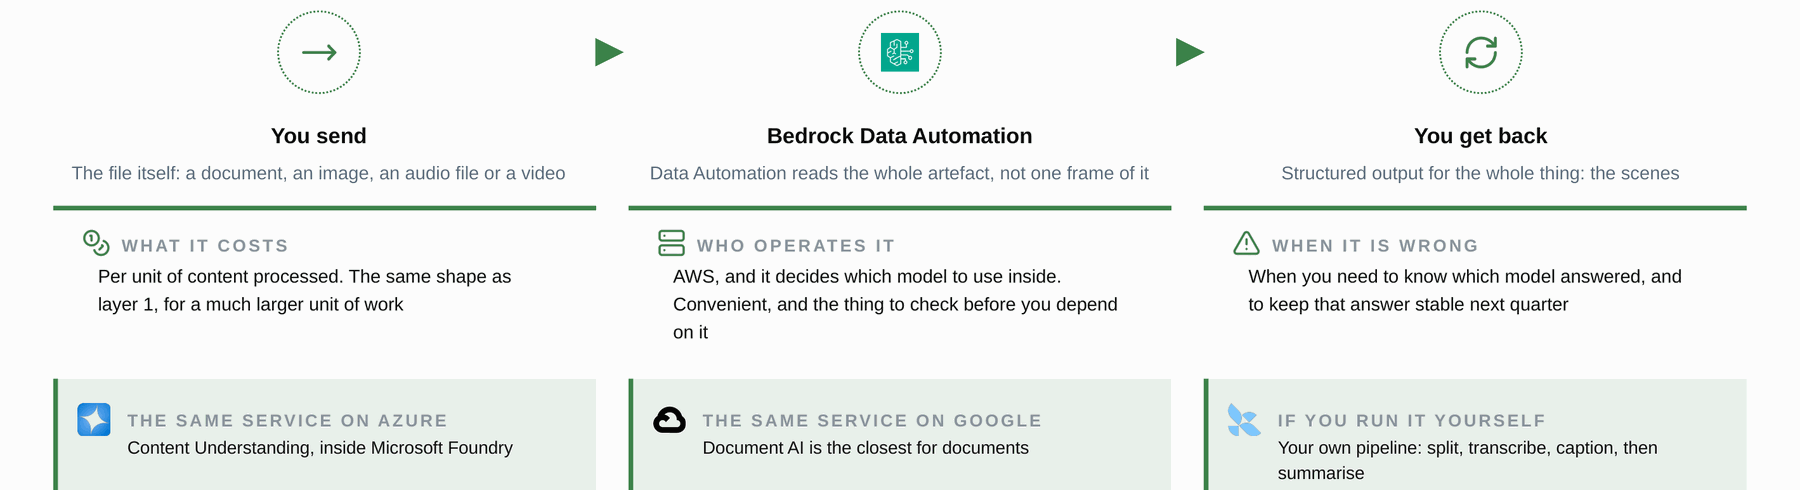
How it looks in an architecture
Slides from my course on AI architectures at FH Burgenland, drawn from real projects.
Where I used it
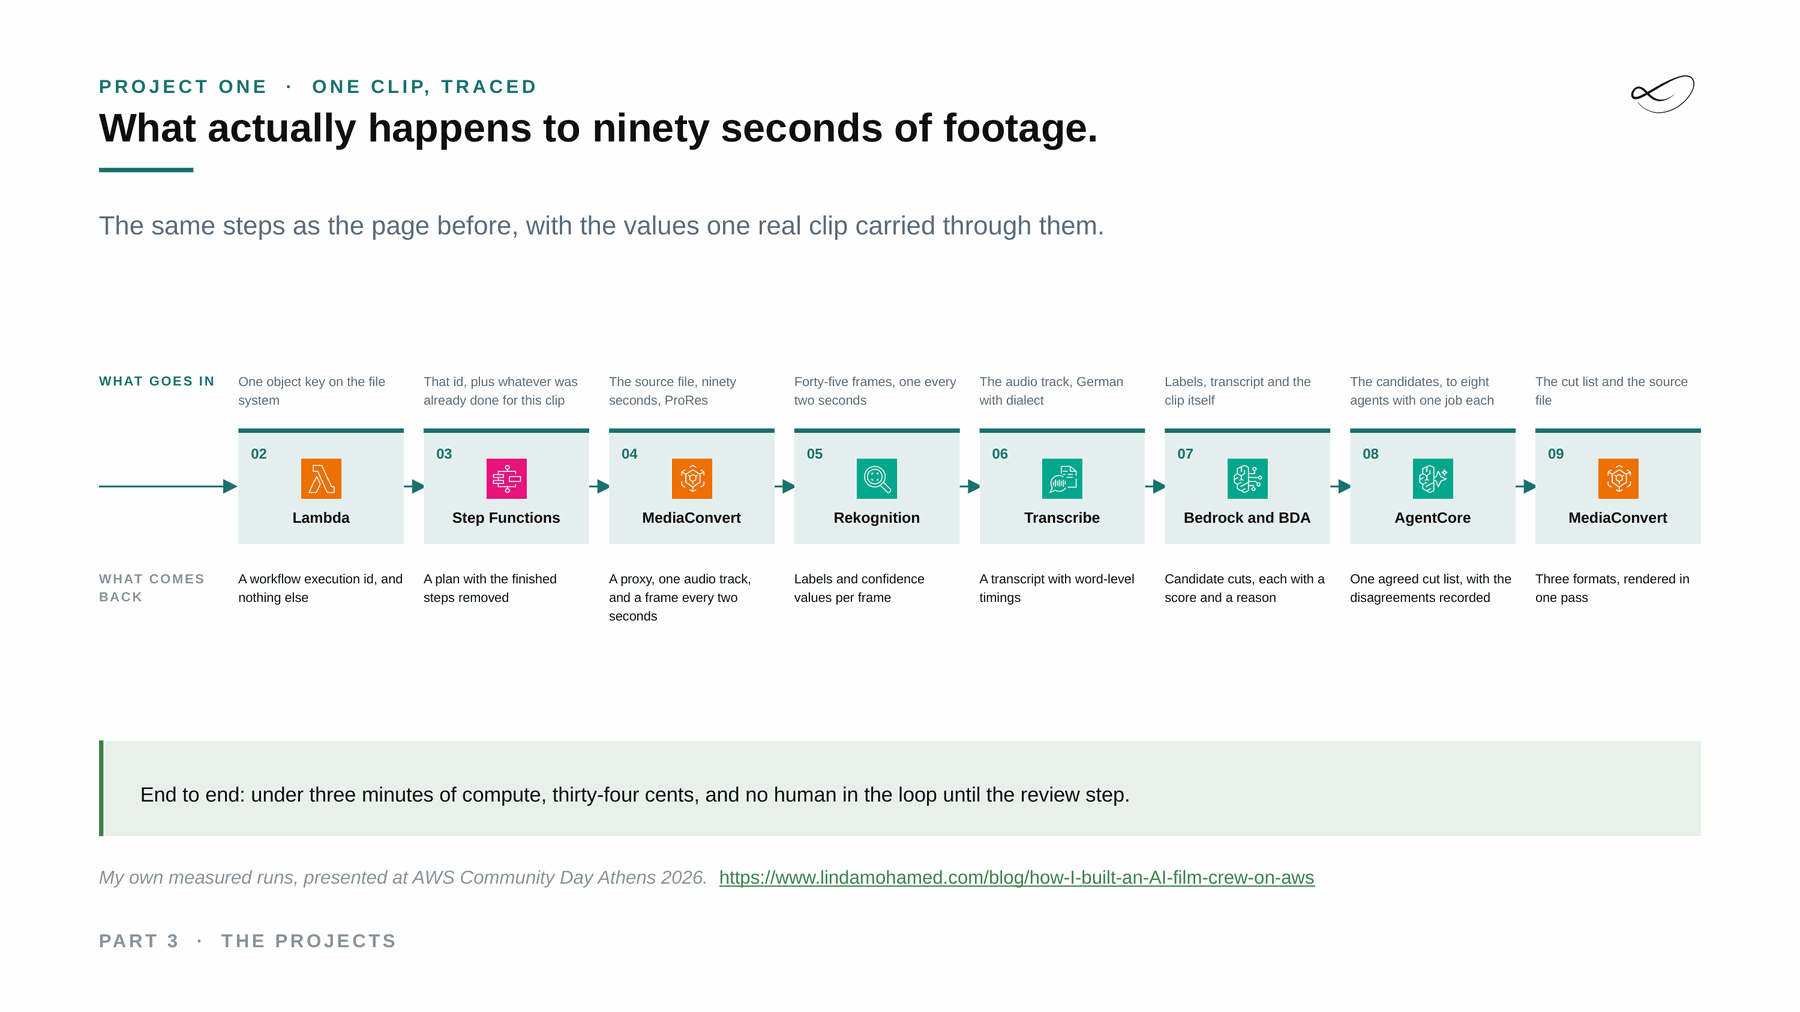
The video pipeline
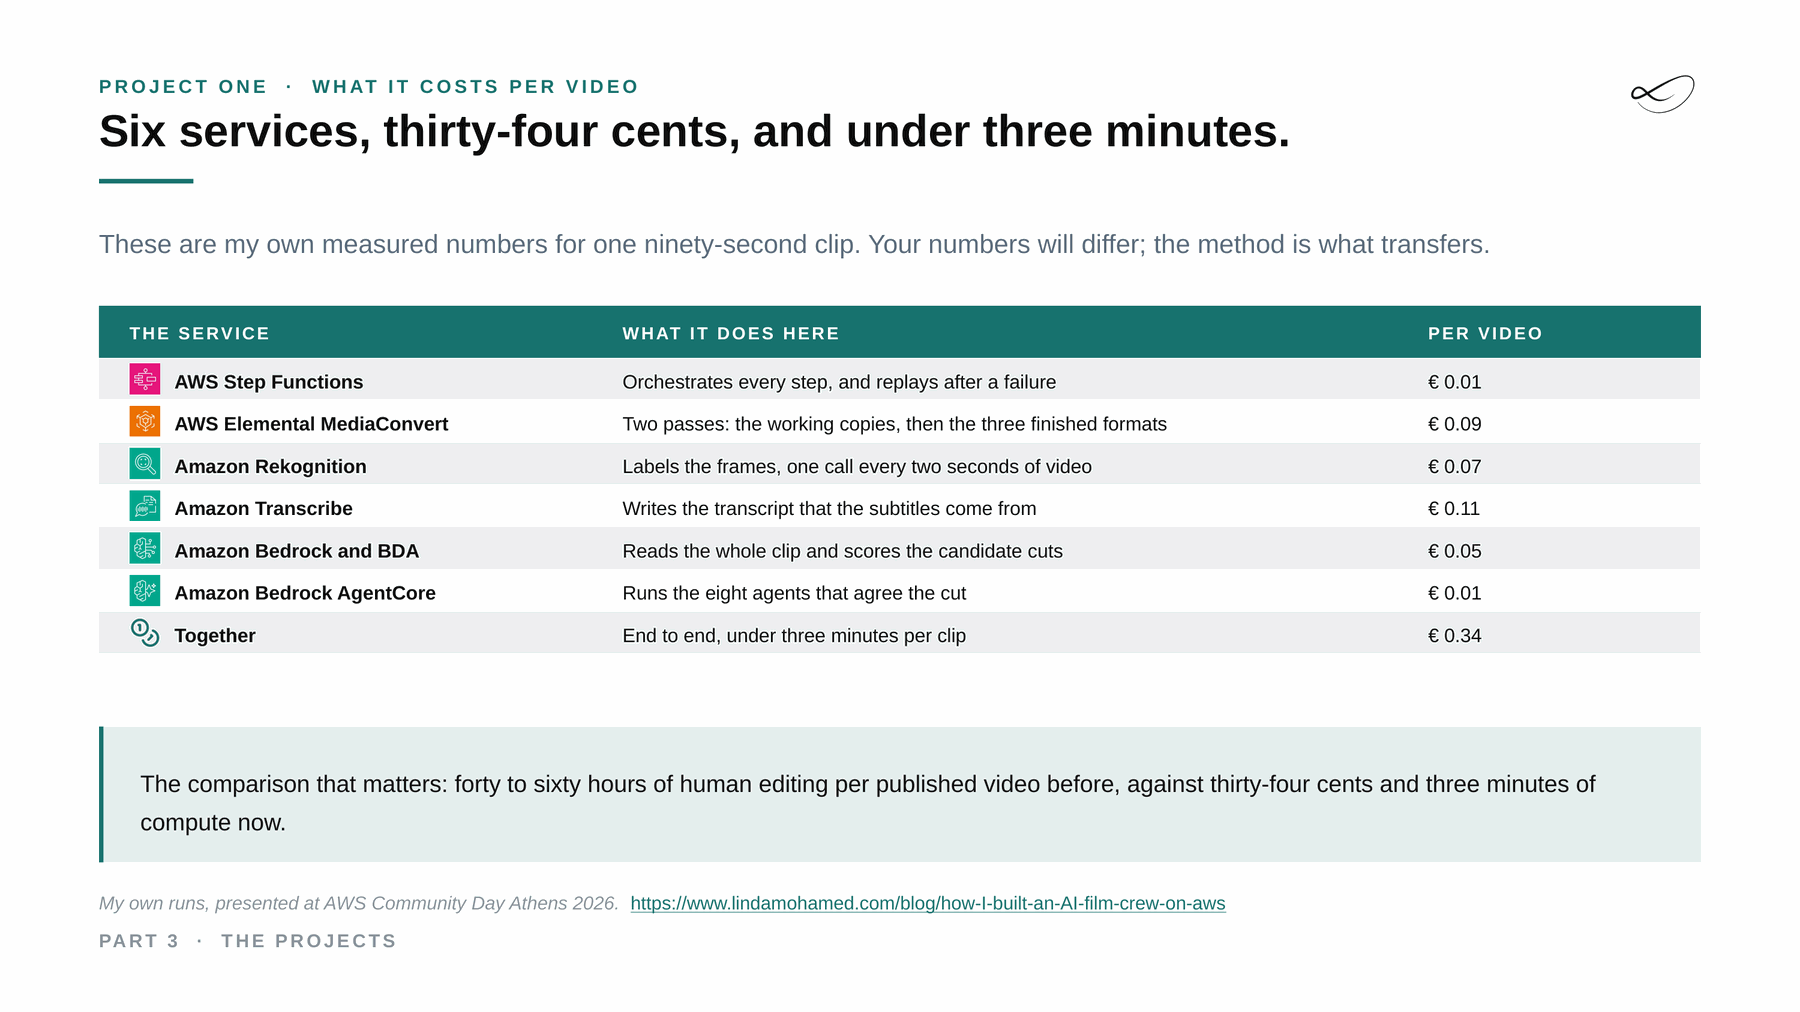
In my video pipeline, Bedrock Data Automation reads each clip as a whole and proposes the cuts. End to end, a finished clip costs about 34 cents and under three minutes, against forty to sixty hours of manual editing before.
Read the write-up →Managed and self-hosted together: hybrid
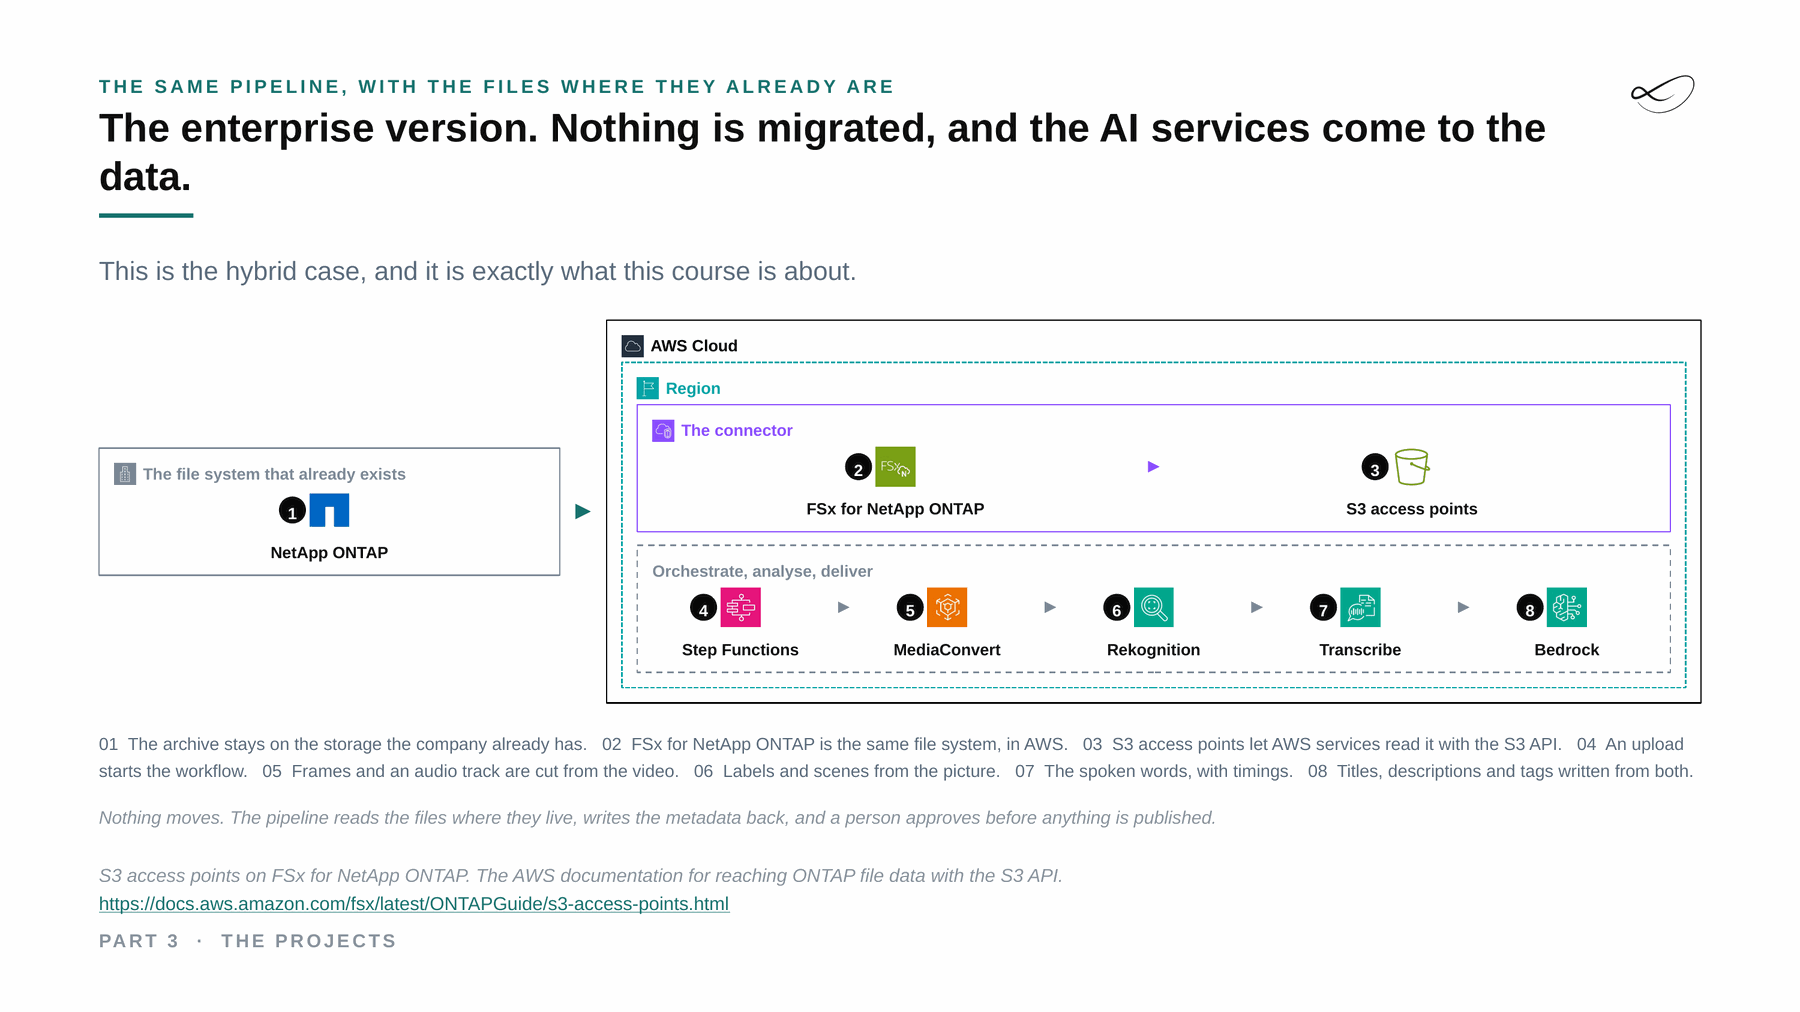
With a ready-made service the call leaves your network. The hybrid decision is what crosses, and in what state: the whole file, a redacted one, or only the part that has to. Where a file may not leave at all, the same step runs with the open-source option inside your building, and only the result, or nothing, crosses.[6]
What would help you next?
Learn to decide
The course “From Managed to Hybrid” teaches where AI should run: what each layer costs, what you operate and where your data has to stay. It is in preparation, with a free live session first.
 Linda Mohamed
AI and cloud consultant, AWS Community Hero, Vienna
Build it with me
Tell me what you want to build. In 30 minutes we check which of the four ways fits your data, your rules and your budget, and whether AWS funding for a proof of concept can cover part of it. How AWS funding works →
You already know what you need
Book the workshop directly:
- AI Concept and Prototype workshops →
Architecture first, priced per service and tested on your data, then a prototype with a go or stop decision. - Generative AI Use Case Workshop →
Which GenAI ideas are worth building, and whether prompts, retrieval or fine-tuning fits each one.

Read more on ai-solutions.wiki
My open knowledge base, with longer comparisons, pricing notes and sources.
Sources
- Amazon Bedrock Data Automation documentation. https://docs.aws.amazon.com/bedrock/latest/userguide/bda.html
- Azure Content Understanding documentation. https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/overview
- Document AI (closest for documents) documentation. https://cloud.google.com/document-ai/docs
- Your own pipeline. https://github.com/docling-project/docling
- Linda Mohamed, course slides “The projects”, MASE-3, FH Burgenland, September 2026
- S3 access points on FSx for NetApp ONTAP, AWS documentation. https://docs.aws.amazon.com/fsx/latest/ONTAPGuide/s3-access-points.html
- Amazon Bedrock, ai-solutions.wiki. https://ai-solutions.wiki/tools/amazon-bedrock/
- OpenAI Whisper, ai-solutions.wiki. https://ai-solutions.wiki/tools/whisper/
- FFmpeg, ai-solutions.wiki. https://ai-solutions.wiki/tools/ffmpeg/
- Pre-built AI services vs foundation models, ai-solutions.wiki. https://ai-solutions.wiki/comparisons/prebuilt-ai-services-vs-foundation-models/
- Azure Content Understanding is now generally available, Microsoft Foundry blog. https://devblogs.microsoft.com/foundry/azure-content-understanding-is-now-generally-available/
Links checked September 2026. Product names and features change: check the linked pages before you decide.